9880
The Voynich Manuscript. The Manchurian Candidate
Voynich Manuscript (VM or VMS) is called the Holy Grail of cryptography. For several hundred years, thousands of man-days have been spent and continue to be spent trying to unravel its meaning and translation. Moreover, very different people have tried, including outstanding world cryptographers. So far, it's not going very well. Two and a half hundred parchment pages, an unknown alphabet, an unknown language, confident calligraphic handwriting, dozens of drawings of unknown plants and naked women bathing in strange canals, zodiacal astrological diagrams - a lot of clues, but so far nothing that would allow deciphering the manuscript. For anyone who has tried to solve the hooks at least a little, the VM appears to be an ideal puzzle - one that has no known solution yet.
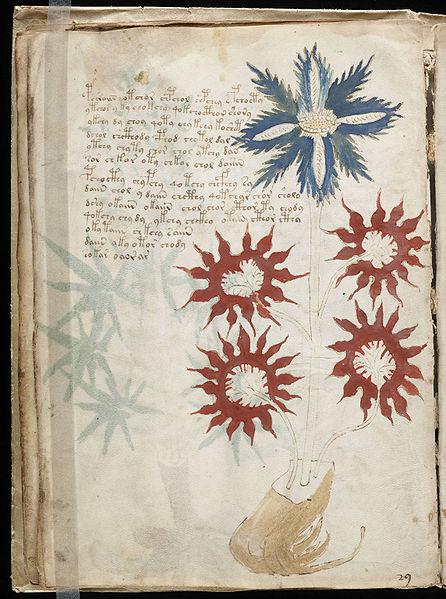
Page 16v
I saw a few months ago a post on Habr about the Aztec language and botanists who identified several Central American plants, but still I'll get my notes out of the drafts. Their goal is to introduce readers to the world of VMS solvers and my not very deep analysis of one of the relatively recent hypotheses - about the Manchurian language of the manuscript.
You can walk around the high-resolution scans here: Voyage the Voynich Manusript
I first encountered the VM from an old article in the paper Computerra, but I wanted to do a little with it now, after the Lenta.ru interview with the author of the latest study, Marcello Montemurro, published on PLoS One. I advise you to familiarize yourself with the articles in Wikipedia and Computerra and the interview on Lenta.
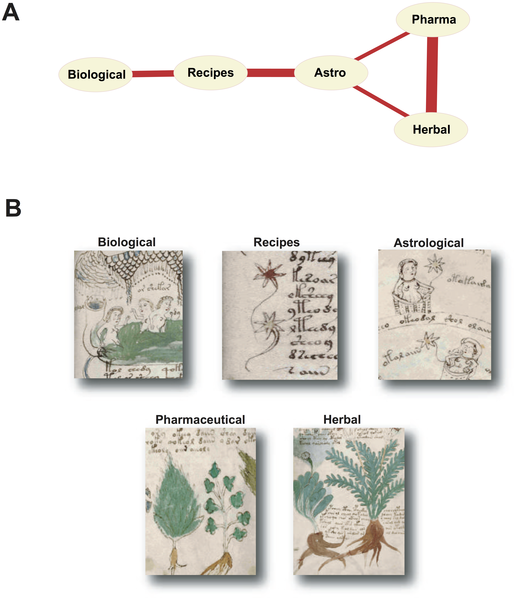
Graph of statistical connectivity between parts of the manuscript - a drawing from Montemurro's article
Throughout the history of deciphering the manuscript, a lot of hypotheses have appeared about its language - from European (one or a mixture of them) and Middle Eastern to completely rare and distant ones, such as ancient Javanese or Indian, whose speakers did not contact Europe in the 15th century; it was not without a translation from ancient Ukrainian. One of the latest "breakthroughs" at the beginning of this year is the deciphering of a dozen words by the British linguist Stephen Bax and attempts to attach some drawings and signatures to Central American endemics and Indian languages. Also, many researchers despaired and decided that the text was a fake or nonsense, gibberish created in order to create fog or impress buyers. But still, there are many more who believe that VM is a real encrypted text. There are reasons to believe that this is so:
1. The presence of a complex text structure. Like all real languages, VM obeys Zipf's law, i.e. the frequency of a word is inversely proportional to its serial number in a sequence sorted by frequency.
2. According to entropic characteristics, the text is close to European languages - Latin, English
I remember in one of Richard Feynman's autobiographical books, his analysis of album sheets of supposedly unknown books with Mayan hieroglyphs is described. In that story, Feynman quickly managed to crack the fake using statistical estimates and logical reasoning. Then he fantasizes with delight - how great it would be if someone dared to create a truly cool fake, taking into account all the patterns in such texts. If someone ever succeeded in such a fake, then it is VM.
In 2003-2004, a Polish researcher Zbigniew Banasik proposed the Manchurian version. I didn't find any links to him, except for his letter about Voynich, only when writing this article I found a publication in a Polish newspaper. Google gives a translation, he is an amateur linguist and polyglot from a village near Wroclaw... He proposed a translation of the manuscript's alphabet into Latin and gave an initial interpretation of the first page. The first page of the manuscript 1r is one of the main targets of attacks on VMS, it is believed that by solving at least part of it, you can get the keys to the entire manuscript.
A short note about the Manchurian language.
There is a article in the Russian Wikipedia. In short, the Manchus are a people who lived in the northern part of modern China and a little of the Far Eastern Russia, originally from the Baikal region and Altai. An older name is Jurchens. In the 17th century, they attacked and captured China, burned Shaolin, founded the Qing dynasty, which ruled until the beginning of the 20th century. During this period, the official paperwork of the Celestial Empire was conducted in the Manchu language, a colossal number of documents accumulated in the Chinese archives, which researchers have not yet reached. It is believed that a good Chinese historian must master Manchu at least in order to read the most important documents of the era in the original. Since the 17th century, the Manchus had an original alphabet, but then they switched to Chinese characters. The Chinese greatly developed the language of the conquerors, added many words to it, translated the Tao Te Ching and Sun Tzu's military treatise into Manchu, and in the late 19th century successfully assimilated Manchuria. Now almost all Manchus speak Chinese, with the exception of a small isolated ethnic group Xibe. Already at the end of the 19th century, the Manchu language was considered endangered, now it can be considered almost dead.
Historically, in Russia in the 19th century. a powerful school of Manchuria studies developed, which, as they write, gave up in the 20th century due to wars and revolutions. On the network, you can find a pdf scan of the deeply developed "Complete Manchu-Russian Dictionary" by I.I. Zakharov published in 1875. But in this case, it is more convenient to use the digitized Manchu-English dictionary of J. Norman. Here you can listen to the song ARKI UCUN with Latin subtitles. As I understand it, the name translates like "let's drink" or something similar.
Manchu officer of the Qing Dynasty, late 1700s, picture from Wikipedia

Description of the methodology
Alphabet and translation
In general, I took a lot from the work that William Porquet did. His page has a large post A Manchu Skeleton Key to the Voynich Manuscript. There are no links to it from the main page there, but it is googled, and I also found a lot of interesting things in the root web folder where the article lies. In addition, he left links to the article on various Voynich forums.
So, taking Banasik's alphabet and its extension, which Porquet proposed, you can translate the text of the manuscript into several versions of the text in Latin with a small number of additional letters. Further, moving on the assumption that we have received some text in the Manchu language or in one of its dialects - extinct or mixed with additional words from another language, we can try to get translation options for each word and phrases from several words. One of the main assumptions is that the words were written by ear or by a person who knows the language without deep knowledge of grammar and spelling - if there was one at the time of creation. This means that one word can be written in several similar variants. This is supported by the especially common endings ain, aiin, aiiin, daiin, etc. in the EVA (European Voynich Alphabet) notation.
First of all, I created a database for text analysis. For a number of reasons, Oracle 11g was chosen. Oracle is mentioned because the query examples will be given in its version of SQL. You can familiarize yourself with the scripts in the Github repository. There is a set of scripts that create a schema, tables, and a number of DML SQL scripts that populate the manuscript tables, the Manchu-English dictionary, and some others.
So, with a simple sequence of regular expressions from text records of the manuscript in EVA and in the extended Banasik alphabet, we get scripts that import VMS line by line, where the row index looks like
<page_numberSIDE_LETTER.row_number>. For example, the second line of the first page of the manuscript has the index
<b><1r.2></b>:
The first 2 lines of VMS in EVA notation look like this (taken from www.voynich.nu/analysis.html):
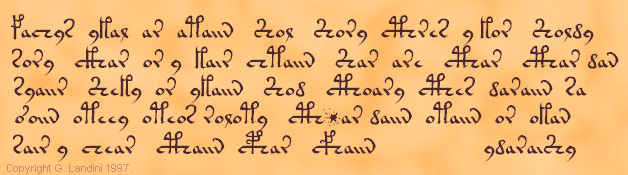
fachys.ykal.ar.ataiin.Shol.Shory.cThres.y,kor.Sholdy
sory.cKhar.or,y.kair.chtaiin.Shar.are.cThar.cThar,dan
The translation will look like this:
'<1r.1> ', 'fachys.ykal.ar.ataiin.Shol.Shory.cThres.y,kor.Sholdy''<1r.1> ', 'cušil i cum us uhungg tom tosi jolkl i cos tombi''<1r.2> ', 'sory.cKhar.or,y.kair.chtaiin.Shar.are.cThar.cThar,dan''<1r.2> ', 'losi gus os i cuks šhungg tus url jus jus bug'The signature at the end of the fifth line of the first paragraph ydaraiShy turns into ibusurti. It seems to me that this is some proper name. There is no such word in the Manchu dictionary, as I found out through a simple search on facebook, it may mean a person from the city of Surat ("sunny city") in southern India - in Russian as a Suratian. True, not in Manchu, but in Hindi or Gujarati…
Similarity function comparison
Words and phrases translated by the table from VMS into Latin must be compared with words from Norman's dictionary. One entry in the dictionary contains one word or phrase of several Manchu words in capital letters and their English translation, which may have several meanings. For example:
CŪŠILE crystal
NIYOHOMBI to have sexual intercourse
CŪŠILE translates the first word fachys on the first page 1r, the second repeatedly flashes in the manuscript, including grammatically correct declensions in Manchu. In the same word, it is convenient to show additional letters: C sounds like a hard "ch", Š - like "sh", Ū - approximately like "yu".
SOUNDEX
To begin with, in order to index and compare the dictionary and the manuscript, I took a simple SOUNDEX function. This is the oldest phonetic algorithm, created back in 1918 and, in my opinion, was used even before computers in the US census. By creating columns with the SOUNDEX index in the dictionary table and in the table where the dictionary fragments of the manuscript are stored, you can look at translation options for it.
Unfortunately, SOUNDEX grabs too much unnecessary stuff. It takes the first 2-3 syllables from the word, translates them into an alphanumeric code, where groups of similar sounds (i.e. letters) are translated into one character. More details - in the link provided in Wiki. But it gives translation options into English! This is the first approximation, and it is very important.
METAPHONE
The development of phonetic algorithms led to the creation of Metaphone and then - Double Metaphone. This is a more advanced version of comparing words. Instead of an alphanumeric code, a purely alphabetic code is calculated from a word or phrase, reduced to one case. Usually vowels are removed, paired or similar consonants are reduced to one representative. All separators and non-letter symbols are ignored. Metaphone appeared at the turn of the 80s-90s, Double Metaphone - in the mid-90s, Metaphone 3 - in 2009. The latter is commercial software, sold together with a small database for comparing names and surnames written in English. There are Double Metaphone implementations for different languages, taking into account the pronunciation of Latin letters and letter combinations in them. There is also one for Russian. There is no one for Manchu. I found a free Double Metaphone implementation in PL/SQL, and expanded it a little, adding the letters described above and a couple more similar ones. It is available in the repository, there are literally a few lines changed. Yes, it will not catch the peculiarities of the morphology of the language with all sorts of declensions, suffixes and prefixes, but even what happened is very interesting.
Connecting the table with the word-by-word slicing of the manuscript and the Manchu dictionary by the METAPHONE code (MPH_CODE) field via LEFT JOIN.
The table below shows the translation options for the first line of the first page <1r.1>. Most words have several options, but for words 5 (uhungg) and 8 (jolkl) there are none.
'<1r.1> ', 'fachys.ykal.ar.ataiin.Shol.Shory.cThres.y,kor.Sholdy''<1r.1> ', 'cušil i cum us uhungg tom tosi jolkl i cos tombi'N — the word number in line <1r.1>
NWORD — word in the proposed alphabet
MPH_CODE — Metaphone code of the word NWORD
WORD — variant of the Manchu word from Norman's dictionary, whose Metaphone code is equal to the code from NWORD
TRANSLATION — translation of the Manchu word
| N | NWORD | MPH_CODE | WORD | TRANSLATION |
|---|---|---|---|---|
| 1 | cusil | CSL | CUSILE | crystal |
| 2 | i | I | I | 1. he, she 2. the genitive particle 3. an interjection used to get the attention of subordinates |
| 2 | i | I | IO | oil, paint, lacquer |
| 2 | i | I | II | see i i |
| 2 | i | I | IOI | 1. a musical instrument made in the shape of a lying tiger--the toothed ridge down the back is stroked with a wooden stick at the conclusion of a musical selection 2. one of the five tones; cf. yumk'a |
| 2 | i | I | I I | 1. (onom.) the sound of sobbing 2. an interjection of derision |
| 3 | cum | CM | CIME | a salt-water fish resembling the salmon |
| 3 | cum | CM | COMO | see coman |
| 4 | us | US | USE | seed, egg (of an insect) |
| 4 | us | US | UCE | door |
| 4 | us | US | USA | exclamation used to get someone's attention |
| 5 | uhungg | |||
| 6 | tom | TM | TOOME | see tome |
| 6 | tom | TM | TOMOO | frame used for weaving nets |
| 6 | tom | TM | TIMU | topic, theme |
| 6 | tom | TM | TOME | (postposition) every, each |
| 6 | tom | TM | TAMA | sole (fish) |
| 7 | tosi | TS | TEISU | 1. assigned place, designated place, responsibility, one's part 2. corresponding, matching, facing, opposite |
| 7 | tosi | TS | TESU | original, local |
| 7 | tosi | TS | TOOSE | 1. weight (for a balance) 2. power, authority, right 3. spindle |
| 7 | tosi | TS | TOSE | see toose |
| 7 | tosi | TS | TESE | plural of tere: those, they |
| 7 | tosi | TS | TES | (onom.) the sound of rope, thread, or a leather thong breaking under stress |
| 7 | tosi | TS | TOSI | white spot on the forehead of an animal |
| 7 | tosi | TS | TSU | vinegar |
| 7 | tosi | TS | TUSA | profit, gain, benefit, advantage |
| 7 | tosi | TS | TUSY | chieftain of a native tribe |
| 8 | jolkl | |||
| 9 | i | I | II | see i i |
| 9 | i | I | IOI | 1. a musical instrument made in the shape of a lying tiger--the toothed ridge down the back is stroked with a wooden stick at the conclusion of a musical selection 2. one of the five tones; cf. yumk'a |
| 9 | i | I | I I | 1. (onom.) the sound of sobbing 2. an interjection of derision |
| 9 | i | I | IO | oil, paint, lacquer |
| 9 | i | I | I | 1. he, she 2. the genitive particle 3. an interjection used to get the attention of subordinates |
| 10 | cos | CS | CECE | silk gauze |
| 10 | cos | CS | CASI | in that direction, thither, there |
| 10 | cos | CS | CESE | register, official record |
| 10 | cos | CS | CISE | vegetable or flower garden |
| 10 | cos | CS | CAISI | see caste |
| 10 | cos | CS | CISU | private, private interest or profit |
| 10 | cos | CS | CISUI | out of one's own interest, on one's initiative, naturally (see also ini cisui), privately, on one's own |
| 10 | cos | CS | COS | the sound of ricocheting or rebounding |
| 10 | cos | CS | CUSE | 1. bamboo 2. silk 3. a cook |
| 10 | cos | CS | CAISE | 1. hairpin 2. a cake made of fried vermicelli |
| 11 | tombi | TMB | TUMBI | to hunt, to pursue |
| 11 | tombi | TMB | TOOMBI | to scold, to rail at, to abuse, to curse |
| 11 | tombi | TMB | TEMBI | 1. to sit 2. to reside, to live 3. to occupy (a post) |
| 11 | tombi | TMB | TAMBI | 1. to get caught on something, to get entangled and trip over something 2. to get caught in a trap or net |
| 11 | tombi | TMB | TUMBI | to hit, to beat, to pound; cf. dumbi |
| 11 | tombi | TMB | TOMBI | see toombi |
As you can see, some words are similar in appearance, some are quite far away, due to the almost complete cutting out of vowels in the code, all variants of Manchu words are issued, which have completely different vowel sounds between the consonants. Short one- and two-letter words are generally "hit or miss". But it's already interesting - much more interesting than searching the dictionary manually with Ctrl-F.
In total, three modifications of the Metaphone were used - the original English one and two more modified ones, with additional letters and changes to the rules for folding.
Transfers to synonyms in the translation field
A small correction of the dictionary - the translation field, containing the transfers "see SOME_OTHER_WORD" through the separator, adds the translation of this synonym.
Transfers to synonyms are caught by a regular expression.
For example, shown above in the table:
TOSE see toose
is immediately supplemented with a translation of the link:
TOSE see toose :: 1. weight (for a balance) 2. power, authority, right 3. spindle
Morphology. Declension of verbs by tense
Let's go further. You can delve deeper into the language. Verbs in Manchu are declined by adding an ending. Here is a declension table with examples and correspondences to English tenses. You may notice that for one English Present Continious or Past Continious there are several different Manchu options. Apparently they reflect some subtleties that I don’t understand or they are just synonyms, but it doesn’t matter for finding matches in Voynich. From the dictionary table, we make and save a selection of verbs in the infinitive form - that is, all words ending in the infinitive ending -MBI and having the substring " to " in the translation field. By removing the ending and saving the result to a separate table, we get a list of verbal Manchu roots MANCHU_VERB_STEM.
For example, the verb AKŪMBI (to die) is saved as: AKŪ.
From the link above, we take the declension table and make a reference table MANCHU_VERB_SUFFIX:
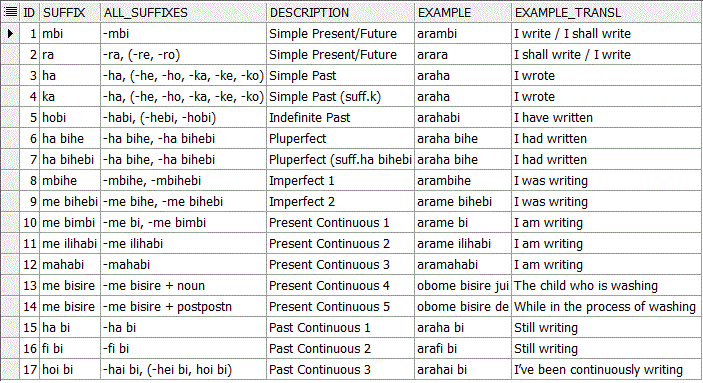
All possible variants of verb declensions are actually the Cartesian product of these tables. Moreover, the search in the manuscript is carried out in exactly the same way, by the Metaphone code, and when declining, the Metaphone code of the suffix ending is added to the code of the verb root. Because of this, you can neglect the different variants of endings for most tenses.
For example, from the declensions of Simple Past in the dictionary, different endings are added to different verbs, but for searching the sliced manuscript, only H or K will be added to the Metaphone code.
Past -ha (-he, -ho, -ka, -ke, -ko), Example: araha (I wrote)
This is what part of the code of the TRANSL_VERBS21 representation looks like, giving translation options for both single- and two-word combinations, taking into account the morphology of verbs: declension options are issued through an internal subquery with UNION ALL:
<code class="sql">SELECT LPAD (
                TRIM (
    REGEXP_REPLACE (idx,
                 '<([[:digit:]]+)([rv]).([[:digit:]]*)>',
                                   '\1')),
               3,   '0')
                                                           lpad1,
             REGEXP_REPLACE (idx, '<([[:digit:]]+)([rv]).([[:digit:]]*)>', '\2')
          lpad2,
             LPAD( trim( regexp_replace(idx, '(\.[:digit:]*)>', '\1') ) , 3, '0')
             lpad3,
             nw.ID,
             nw.id_type,
             nw.n_type,
             nw.idx,
             nw.n,
             nw.nword,
             nw.sound_code,
             nw.mph21_code,
             v.word,
             v.translation
        FROM VMS.gonk2_nword nw
             LEFT JOIN
             (SELECT VS.STEM || suff.suffix WORD,
                     suff.description || ' : ' || VS.TRANSLATION translation,
                     metaphone21 (VS.STEM || suff.suffix) mph21
                FROM VMS.MANCHU_VERB_STEM vs
                     CROSS JOIN VMS.MANCHU_VERB_SUFFIX suff
               WHERE suff.suffix <> 'mbi'
              UNION ALL
              SELECT D.WORD, D.TRANSLATION, D.MPH21_CODE
                FROM VMS.MANCHU_DICT_JOIN d) v
                ON NW.MPH21_CODE = v.mph21
       WHERE nw.n_type IN (1, 2) </code>
Example. In Manchu grammar, there are many more options for changing verbs using suffixes, but digging too deep took too much effort, so let's just look at how the morphology of the verb NIYOHOMBI is revealed:
<code class="sql">select * from VMS.TRANSL_VERBS21 rt where 1=1
  and (   word like '%HOMBI%'
  or translation like '%niyohomb%'
   or word like '%NIOH%'
    )
   and n_type = 2 </code>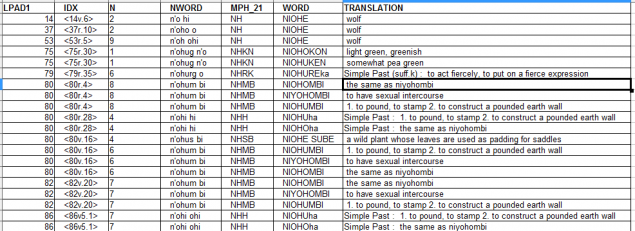
Results
Intersection with words from the Swadesh list
Swadesh lists are basic vocabulary, sets of basic words by which linguists assess the relationship between two or more languages. For example, here is a table comparing Slavic languages according to the Swadesh list. Also, the tables estimate the rate of language change over time. Basic words from such lists are replaced or changed much less often than others, but from time to time they also do. For example, in the Russian language the word "eye" is alluvial, almost slang, it came to replace the common Slavic word "oko" in some 13th or 14th century. Originally it meant a pebble with a hole inside. The eyes remained in poetry, proverbs and church texts. There are Swadesh lists for 100, 200 and 215 words. They write that linguists use the shortest list of 100 words the most. If you are interested, here is Morris Swadesh's biography in Russian.
Just for interest, I wrote down a large English-Manchu list of 207 words in a separate table and intersected with all translations of all sets of 1 and 2 words from the manuscript, sorting by frequency. Here is the table that came out - these are the top 33 most frequent words. Not everything is
"Dauria" in space
Summary of the Soviet space exploration, types of rockets and the most significant victories in this field. Part 2